𝗩𝗟𝗠𝘀 - 𝗧𝗵𝗲 𝗙𝘂𝘁𝘂𝗿𝗲 𝗼𝗳 𝗔𝗜 𝗶𝘀 𝗔𝗯𝗼𝘂𝘁 𝘁𝗼 𝗚𝗲𝘁 𝗘𝘃𝗲𝗻 𝗠𝗼𝗿𝗲 𝗩𝗶𝘀𝘂𝗮𝗹!
We’ve come a long way from traditional LLMs (Large Language Models) that could only understand textual data. But now, the AI world is rapidly evolving — and 𝗩𝗟𝗠𝘀 (𝗩𝗶𝘀𝗶𝗼𝗻-𝗟𝗮𝗻𝗴𝘂𝗮𝗴𝗲 𝗠𝗼𝗱𝗲𝗹𝘀) are leading the charge. 🔥
Unlike LLMs, VLMs can process both text and images, opening up new dimensions for how we interact with machines. Think beyond text prompts — now imagine AI that can understand your documents, screenshots, design files, and even the code in your IDE.
:) Remember the viral Ghibli-style image trend? That was just the beginning. We've already seen powerful VLMs like:
• GPT-4V (OpenAI)
• Gemini 1.5 Pro (Google)
• LLaVA-NeXT showing remarkable capabilities in interpreting and generating content from both text and visuals. The image below is also by a VLM processing :)
👉 But what’s next? Here’s where it gets even more exciting:
𝗜𝗺𝗮𝗴𝗶𝗻𝗲 𝘁𝗵𝗶𝘀 — you're coding in VS Code, and without typing a single prompt, your AI assistant understands your screen, analyzes your current project, and suggests the next lines of code or optimizations in real time. No more manual context-giving. No more copy-pasting errors. Just seamless, intelligent assistance.
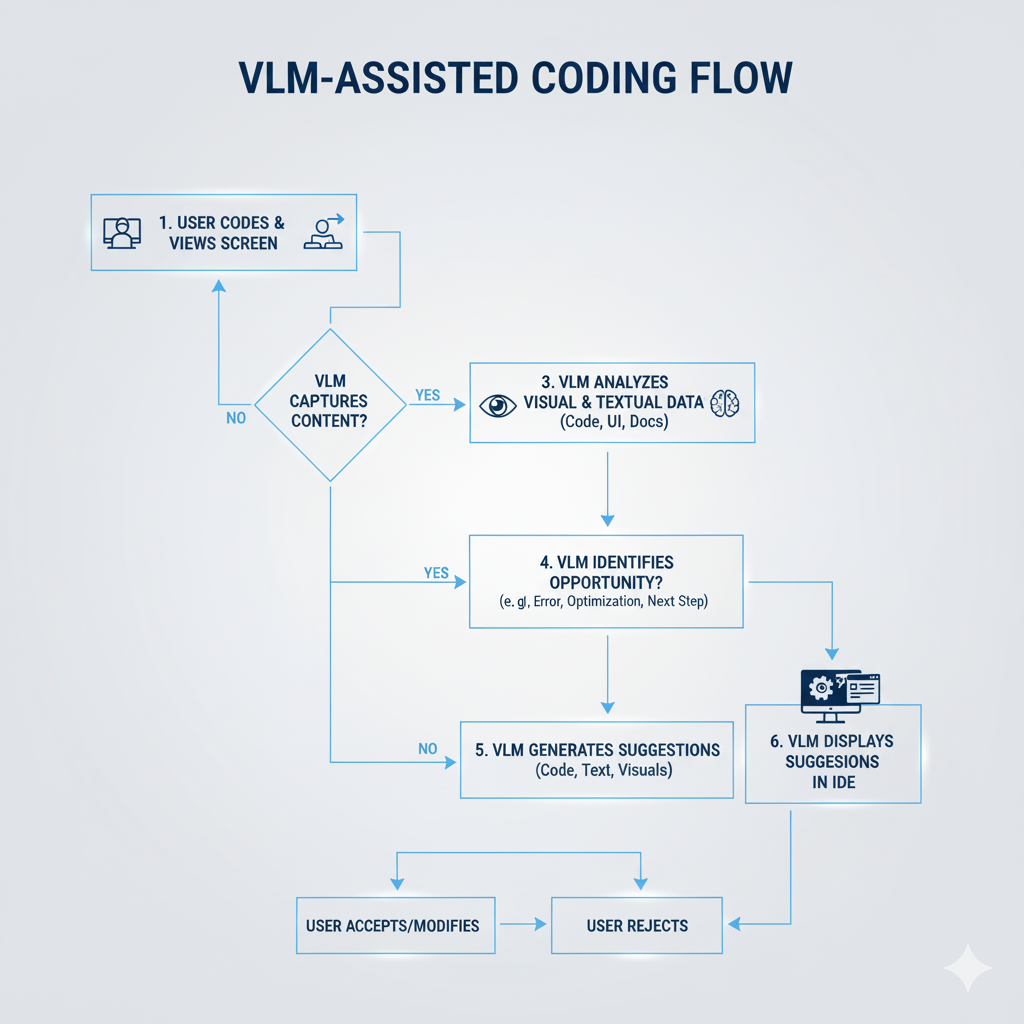
This is the next evolution in 𝘼𝙄: 𝘼𝙄 𝙩𝙝𝙖𝙩 𝙨𝙚𝙚𝙨 𝙬𝙝𝙖𝙩 𝙮𝙤𝙪 𝙨𝙚𝙚. And it's not a distant dream — it’s already in the works.
Companies like Google (Gemini), Qwen (Alibaba), Anthropic (Claude), and others are aggressively building toward this future.
Key Takeaways:
• VLMs = Vision + Language = Multimodal Intelligence
• Big shift from text-only input to full-screen context
• Real-time coding, design, and workflow assistance
• The future of human-AI interaction will be frictionless
